Guidance needed to recover an idea’s essence
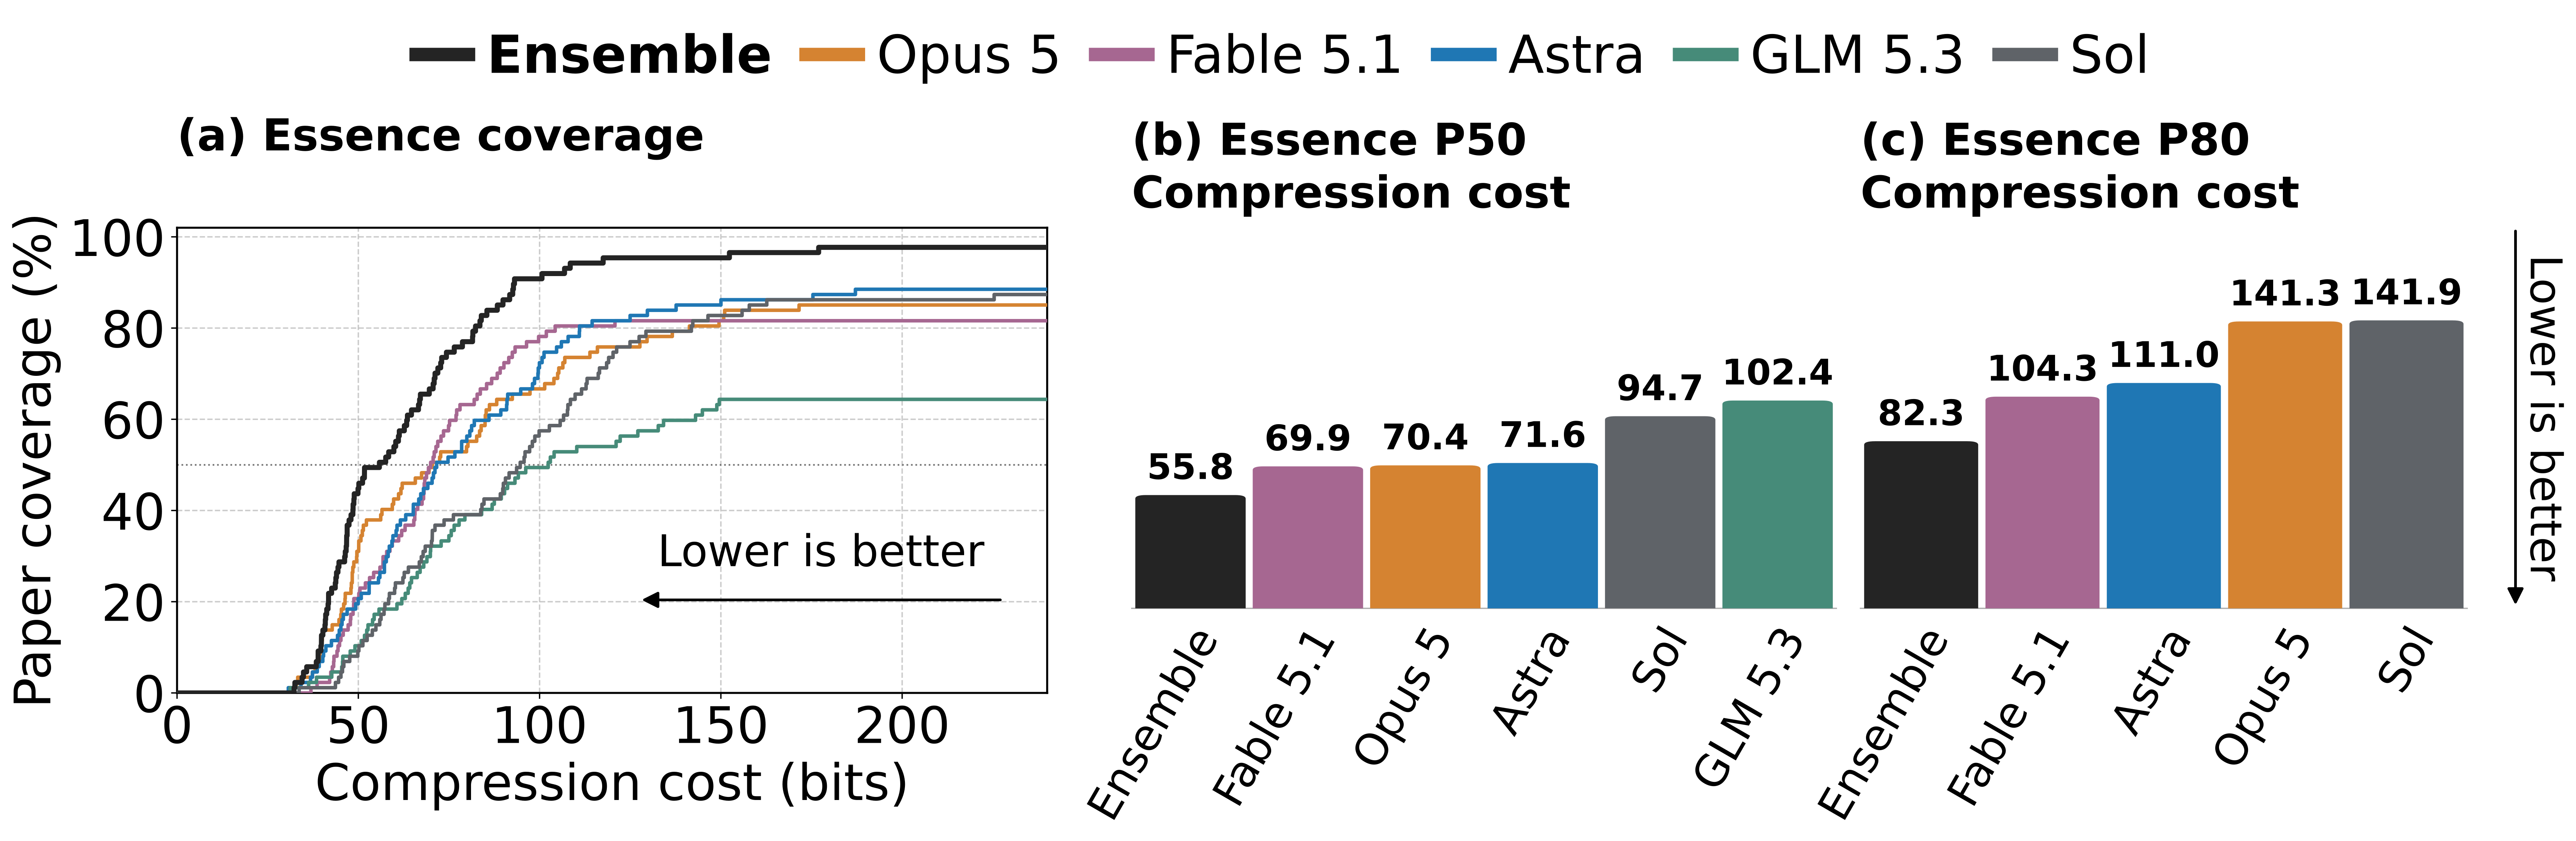
Fable 5.1 has the lowest individual median Essence compression cost, 69.9 bits; the three-model ensemble reaches 55.8 bits.
87 selected recent deep-learning papers. Panel a: fraction recovered versus guidance bits; panels b/c: minimum cost covering 50%/80% of all targets. Lower is better. Fable 5 is the guide; GPT-5.5 judges Essence. Unsuccessful targets remain uncovered.
View original chart and methods ↗
Priced Guidance: Can Language Models Generate Future Research Ideas? · Figure 2; Sections 3–4 and 6
How to interpret this chart
- Guided reconstruction, not measured unaided discovery frequency or proof that an idea works.
- Scores depend on generator, guide, scaffold and LLM judge; judge pass is not scientific validation.
- Title-recall screening reduces but cannot prove absence of memorization.
- GLM 5.3 did not reach 80% Essence coverage within the guide budget; its missing P80 is not zero.
- The 18,000-fold claim concerns an implied probability lower bound, not measured research productivity.
Published values from the chart
Printed Figure 2 labels; P50/P80 refer to target coverage, not confidence intervals. No missing value was converted to zero.
| Generator / ensemble | Essence P50 (bits) | Essence P80 (bits) |
|---|---|---|
| Fable 5.1 + Opus 5 + Astra ensemble | 55.8 | 82.3 |
| Fable 5.1 | 69.9 | 104.3 |
| Opus 5 (high) | 70.4 | 141.3 |
| GPT-6 Astra | 71.6 | 111.0 |
| GPT-5.6 Sol | 94.7 | 141.9 |
| GLM 5.3 | 102.4 | Not reached |