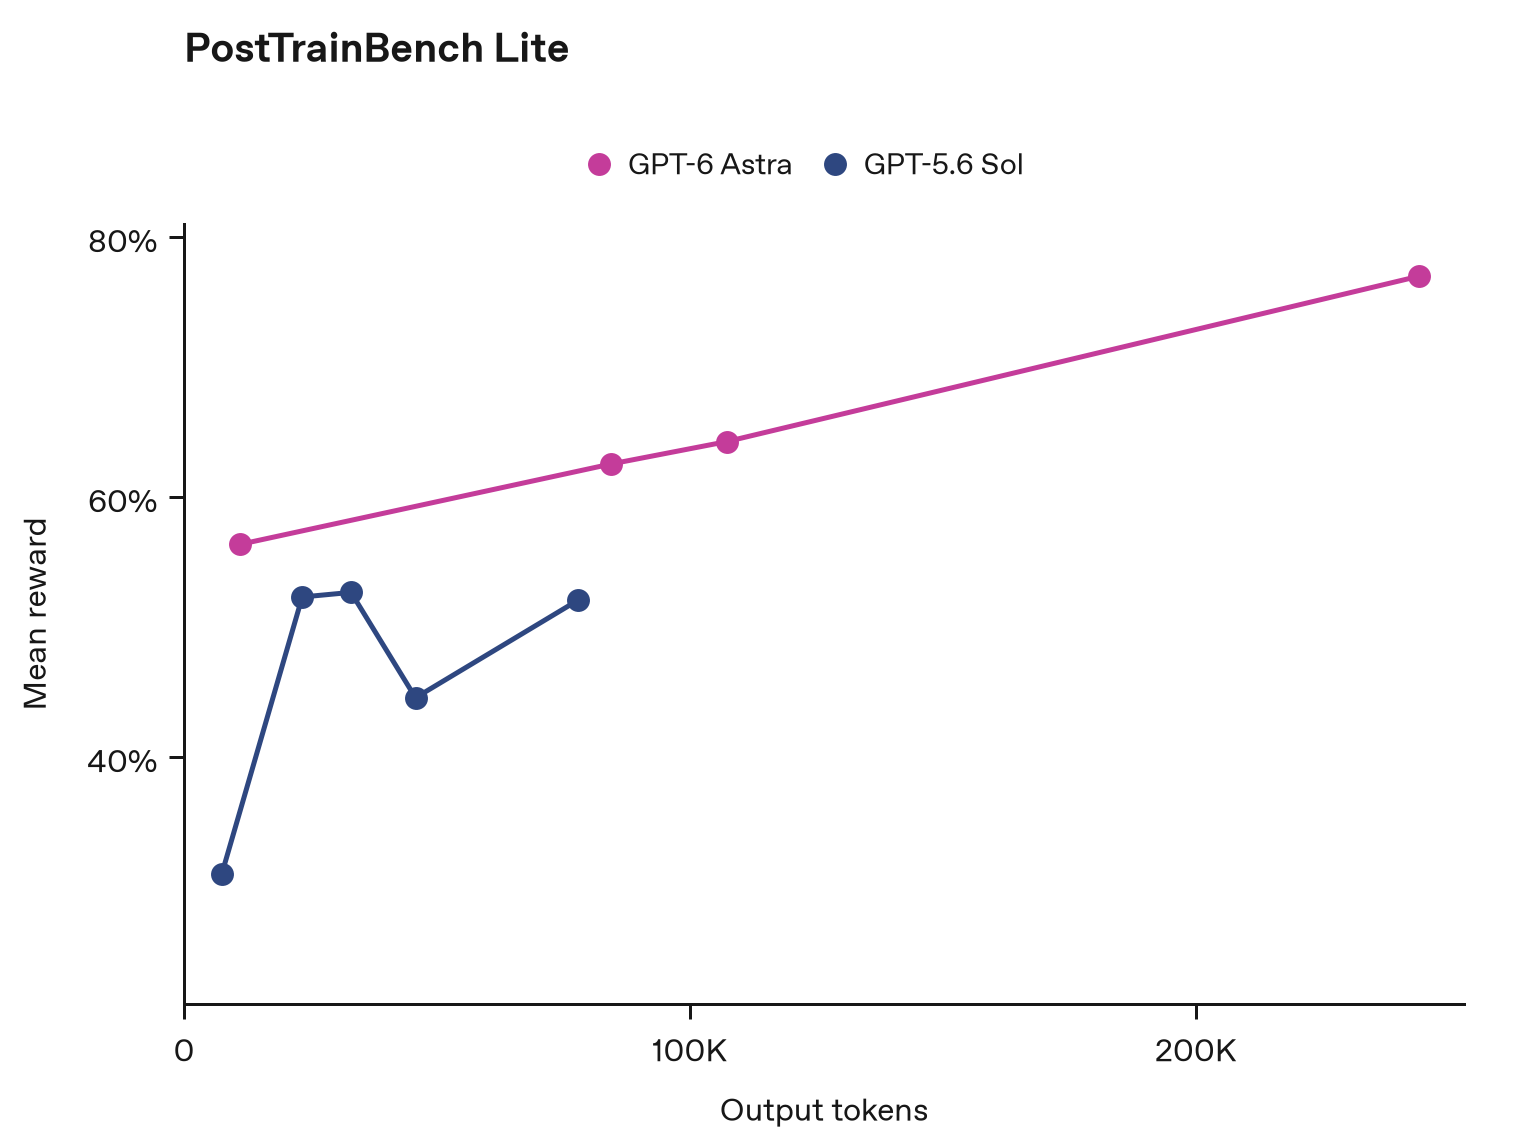
Training improvements at different token budgets
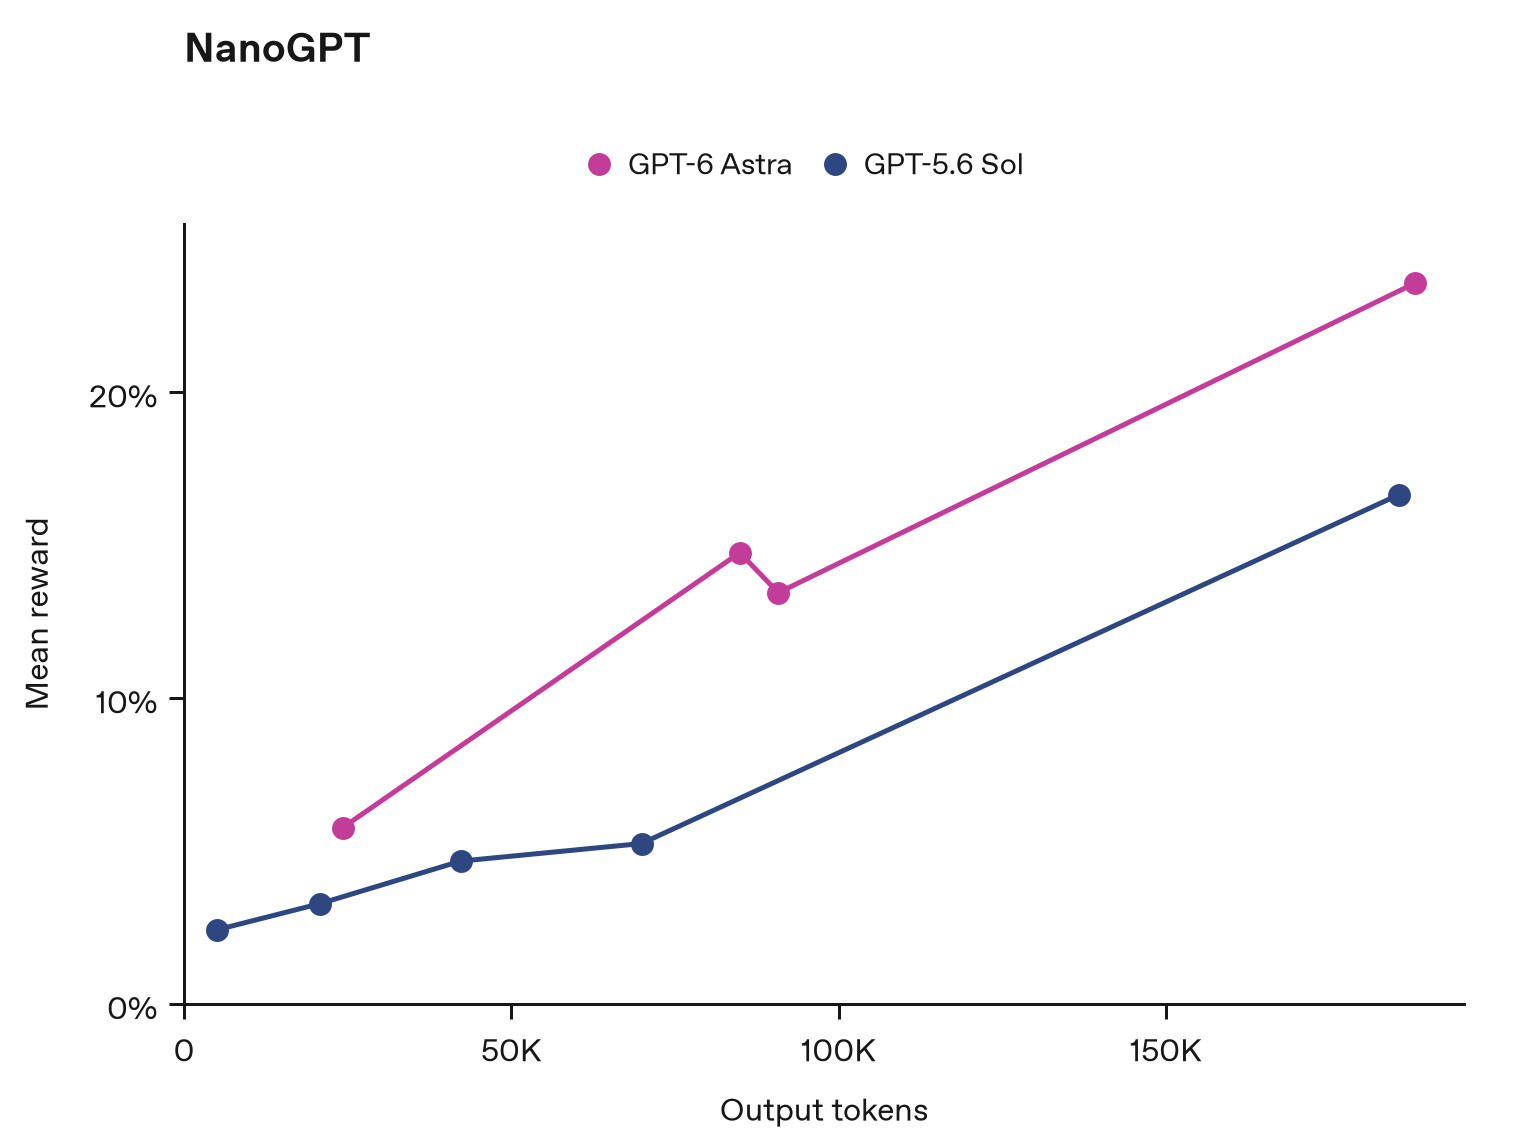
NanoGPT compares GPT-6 Astra and GPT-5.6 Sol on improving a small language-model training setup. The curves show how reported reward varies with the output-token budget.
Mean reward against output tokens in OpenAI’s NanoGPT evaluation. The budget is part of the result; this is not a single comparable score.
View original chart and methods ↗
GPT-6 Astra System Card · Section 10.1.3.3, Figure 54
How to interpret this chart
- Exact point values are not printed. The tracker retains the figure rather than estimating scores from its geometry.
- This is a task-specific training evaluation, not evidence of an autonomous improvement loop.